Case Study
The ₹12 Question
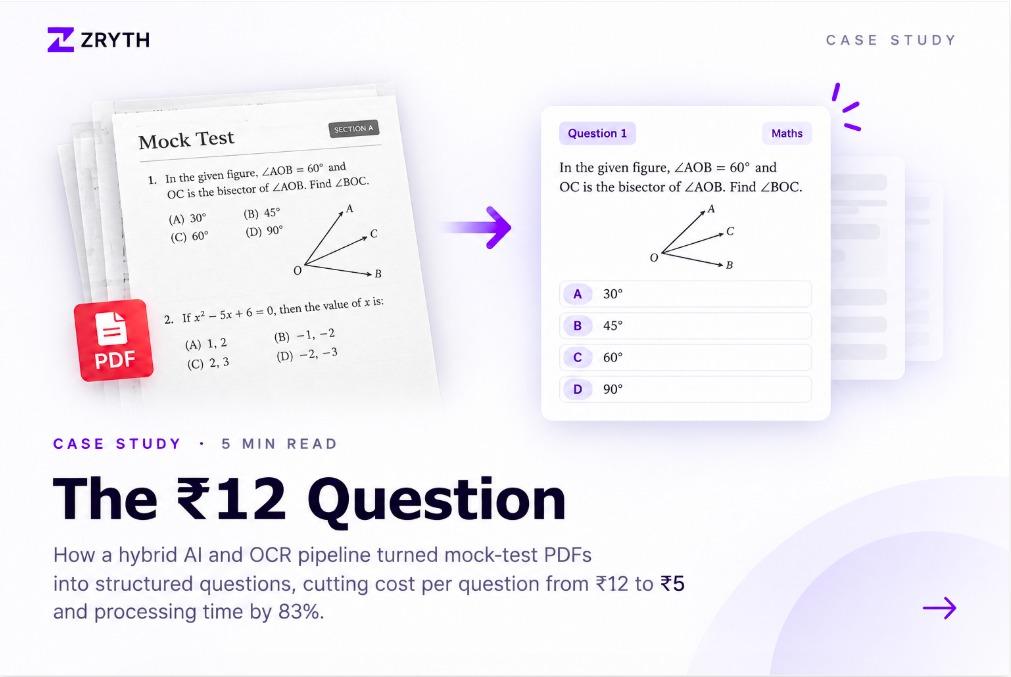
How a hybrid AI and OCR pipeline turned mock-test PDFs into structured questions, cutting cost per question from ₹12 to ₹5 and processing time by 83%.
Zryth Research · September 2026 · 5 min read
Twelve rupees, one question at a time
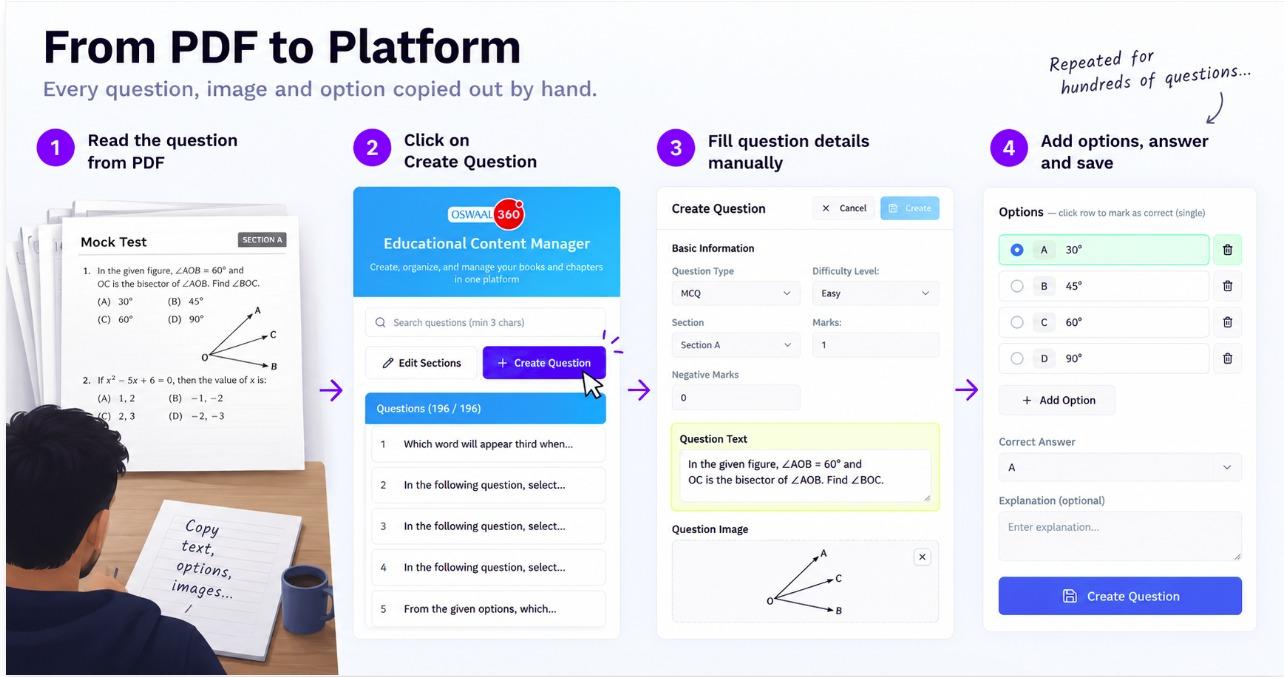
An education client was building mock tests at scale, and every question in every PDF had to be converted into a digital format by hand: text, images, options, answers, all copied out manually. That process cost roughly ₹12 per question.
The cost didn't stay small for long. 100 questions came to about ₹1,200. At 1,000 questions, it was ₹12,000. At 10,000, it was ₹1,20,000. There was no volume discount, the cost just kept scaling in a straight line with the work.
A question is more than just text
Before proposing anything, we sat down with the client's existing workflow rather than just looking at the PDFs in isolation. A single question could carry question text, images, multiple options, option images, section information, an answer, negative marking, hints and explanations, all of it tied together.
The difficulty scaled with the question. A plain text question was straightforward. A question with a diagram, a mathematical expression, a reasoning puzzle, or a mix of text and images was a different problem entirely.
Why one extraction method wasn't going to be enough
We reviewed the process across many different mock-test PDFs and mapped out where automation could actually help: reading the PDF, extracting text, extracting images, identifying questions and options, detecting question structure, preserving mathematical and LaTeX content, handling image-based questions, mapping everything into the right structure, and validating accuracy at the end.
That mapping made one thing clear early on: no single OCR or text-extraction technique was going to handle all of it. We designed a multi-stage AI workflow instead.
Building a pipeline that adapts to the question
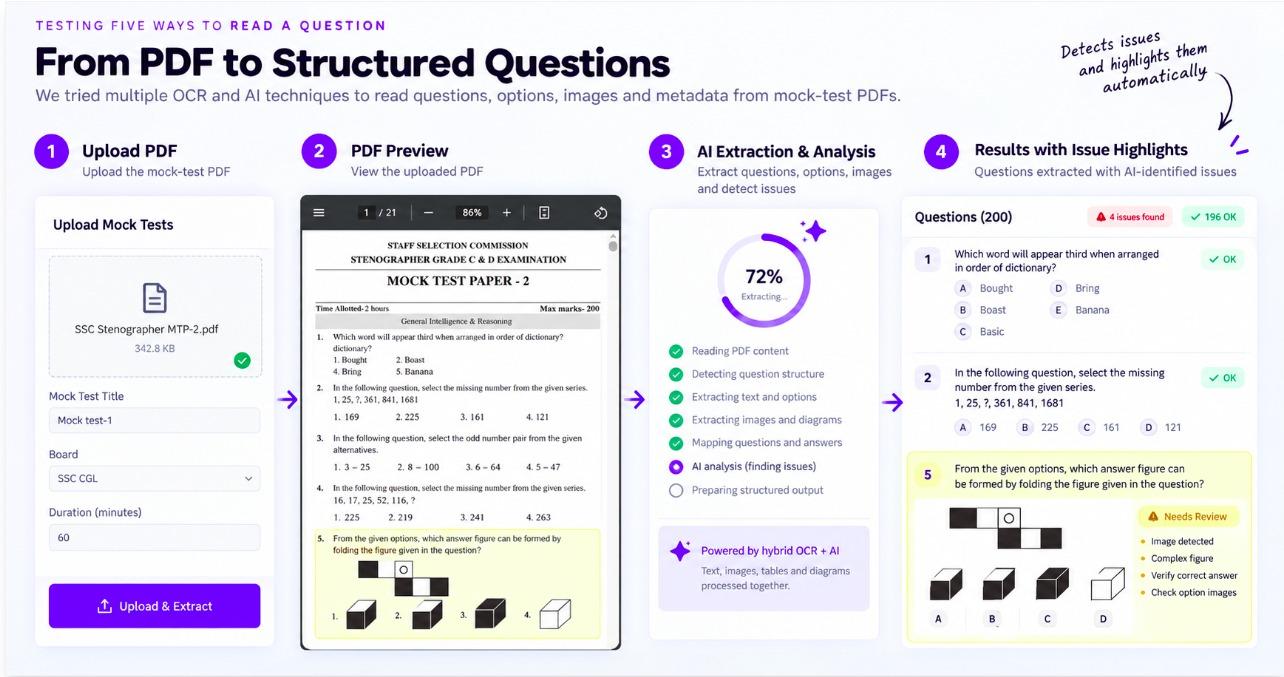
The pipeline analyses each PDF to identify text, images, mathematical expressions, diagrams and mixed content, then extracts question text, options and images while keeping each one tied to the right question. Different AI models and OCR techniques are applied depending on the content type, mathematical expressions and LaTeX are preserved rather than lost, and the result is structured output, questions, options, answers, images, sections, explanations and negative marking, ready to load straight into the client's question bank.
Testing five ways to read a question
Conventional PDF libraries and OCR handled simple text well but struggled with complex layouts, images, reasoning questions and mathematical content. Trying several OCR techniques improved raw text extraction, but none of them could reliably understand how a question, its options and its images related to each other.
AI and LLM models were better at identifying structure, questions, options, answers, explanations, sections and metadata, and separate image-analysis models were better at reading diagrams and figures. No single one of these covered every case on its own.
Why the hybrid approach won
The final system routes each question by content type: text-heavy questions go through text extraction plus AI analysis, image-heavy questions go through image extraction plus image analysis, and mixed questions get both. That hybrid routing outperformed every single-technique approach we tested.
In testing, theory and text-based questions reached close to 100% extraction accuracy, while questions involving reasoning, diagrams or more complex images reached around 95%. The hybrid approach won because it balanced accuracy, image preservation, structure recognition, mathematical content and scale, rather than optimising for just one of them.
The result: fewer hands, faster turnaround, lower cost
Cost per question dropped from roughly ₹12 to ₹5, a reduction of about 58%. Processing 100 questions, which used to take around 12 hours, now takes about 2 hours, a reduction of roughly 83%.
The work also needs fewer people. Instead of several people manually entering and cross-checking questions, one person mainly reviews the automated output, and because the system extracts and structures content consistently, accuracy improved rather than dropped.
The takeaway
The biggest success was turning a slow, expensive, manpower-heavy manual process into a largely automated workflow, one that got both cheaper and more accurate at the same time, and that now scales to thousands of questions without scaling the manual effort alongside it.
Zryth Research
How a hybrid AI and OCR pipeline turned manual mock-test question entry into an automated workflow, cutting cost per question by 58% and processing time by 83%.